EByte Case Study Editing WAV and ZIP Files Without Fixing Sizes by Hand
Every earlier case study ended with the same chore. Change the length of anything and some size field elsewhere in the file goes stale, and you fix it yourself: riff_size in a WAV, the name lengths and the directory offset in a ZIP. EByte 0.3.0 adds derived sizes and offsets, so the schema can say where those numbers come from and the encoder works them out. This case study tried it on the same WAV and ZIP samples as before, using the released ebyte 0.3.0 Linux binary downloaded from GitHub. Its checksum matched SHA256SUMS before anything ran.
The idea is a short list of things a size can be: the length of one field, the length of a run of fields, the offset where a field starts, or the number of blocks in a repeat, plus an optional constant. There’s no other arithmetic. A size field that a later field takes its length from is simply written from that field’s value, the way array counts already were.
Two Lines in the WAV Schema
The riff-wave schema gained two derive entries. riff_size is the size of everything from the WAVE tag to the last chunk, and each chunk’s size is the size of its body:
{"name": "riff_size", "type": "u32", "derive": {"size_of": {"from": "wave", "to": "chunks"}}},
...
{"name": "size", "type": "u32", "derive": {"size_of": "body"}}
Decoding the 1,696-byte sample now gives a document with no riff_size and no chunk sizes in it. They’re still in the trace (1688, 16, 1600 and 44), just not something you can edit.
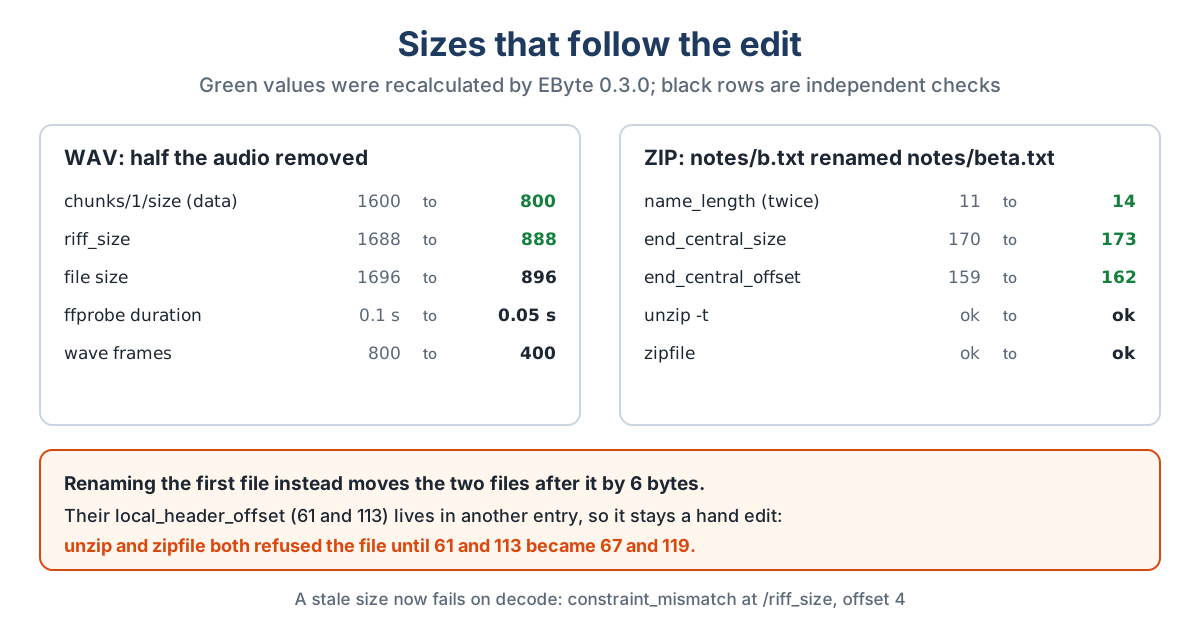
Half the audio. Cutting the data body from 1,600 bytes to 800 produced an 896-byte file. EByte wrote 800 into the chunk size and 888 into riff_size, which is the file length minus 8, as it should be. ffprobe reported 0.05 seconds with both tags intact, and Python’s wave read 400 frames.
A new chunk. Appending a chunk with id note and the 16-byte text “EByte 0.3.0 note” made a 1,720-byte file with riff_size 1712 and a chunk size of 16, both written by EByte. ffprobe and wave read it as before: 0.1 seconds, 800 frames, same tags.
Stale Sizes Now Fail
There’s a price. In the 0.2.0 case study, removing the LIST chunk without fixing riff_size left a file that claimed 52 bytes more than it had, and both players accepted it anyway. The 0.3.0 schema doesn’t:
{"diagnostic_version":1,"stage":"decode","code":"constraint_mismatch","path":"/riff_size","offset":4,"field_start":4,"expected":"stored value equals measured fields","observed":"stored value differs"}
That’s on purpose. A derived value isn’t in the document, so if EByte accepted a wrong one, encoding would quietly correct it and the round trip would no longer give back the same bytes. To read a file like that anyway, delete the derive from that field and it becomes an ordinary integer you edit yourself.
ZIP: Most of the Bookkeeping
The zip schema now derives every name, extra and comment length, the compressed data length, both entry counts in the end record, and the central directory’s size and offset. The sample is three files, 362 bytes.
Renaming the last file. notes/b.txt became notes/beta.txt in both its local header and its directory entry, the only two edits in the JSON. EByte wrote 14 into both name lengths, moved the directory size from 170 to 173 and its offset from 159 to 162. unzip -t found no errors and Python’s zipfile read all three files.
Changing the archive comment. A longer comment set the comment length to 36 and nothing else, and both tools read the result.
Renaming the first file. This one shows where 0.3.0 stops. readme.txt became README-first.txt, six bytes longer, which pushes the other two files six bytes further into the archive. Each directory entry records where its file’s local header starts, and that number belongs to a different entry than the one it measures. Derived values only look at their own siblings, so local_header_offset stayed at 61 and 113. unzip refused the result with “invalid zip file with overlapped components” and zipfile raised BadZipFile. Changing the two offsets to 67 and 119 by hand fixed it, and both tools read every file.
What’s Still by Hand
In the library schemas: a ZIP entry’s local header offset, its sizes as repeated in the central directory, and its CRC-32. In WAV, byte_rate and block_align, which are products of other fields. In BMP, width and height have to match the pixel data. The schema library lists these for each schema. Checksums are the next planned release, and the schema reference covers every derive form.